AI Insights
/repos/[owner]/[repo] · /org/[orgName]/healthNew in v4.1.0An optional layer that turns the metrics already on screen into plain-English analysis — what changed, why it matters, and what to do next. It appears as a collapsible card on the Repository Overview and Team Health Scorecard pages.
Anomaly explanations
New in v4.1.1On the Workflow Detail Reliability tab, each flagged metric gains a “Why did duration spike?” button. It explains the outliers from surrounding metadata — baseline statistics, when the workflow file last changed, and the mix of triggers — then suggests one concrete check you can run yourself.
The request is lazy — opening the Reliability tab costs nothing until you click. Results are cached for 30 minutes.
Failure hypotheses
New in v4.1.2When a workflow has 3 or more recent failures, the Reliability tab offers “Suggest why this is failing” — up to three ranked likely causes, each with the evidence behind it and a confidence level. Below that threshold the feature stays quiet: speculating about one flaky run is noise, and the floor is enforced server-side, not just hidden in the UI.
| Signal used | What it suggests |
|---|---|
| A workflow-file change dated just before the first failure | Someone changed the pipeline — usually the answer |
| One step failing far more than the rest | A flaky or newly-broken step, rather than the environment |
| Failures clustered on one trigger or branch type | A context-specific problem (PR-only, main-only) |
| A shift in run duration | Timeouts, early exits, or infrastructure pressure |
| A long success streak ending abruptly | Something changed at a knowable point in time |
Cost is kept proportional to the problem: job detail is fetched only for runs that actually failed, capped at 10, and the GitHub fan-out is cached separately from the generation. This surface is rate-limited to 10 requests/minute — half the others.
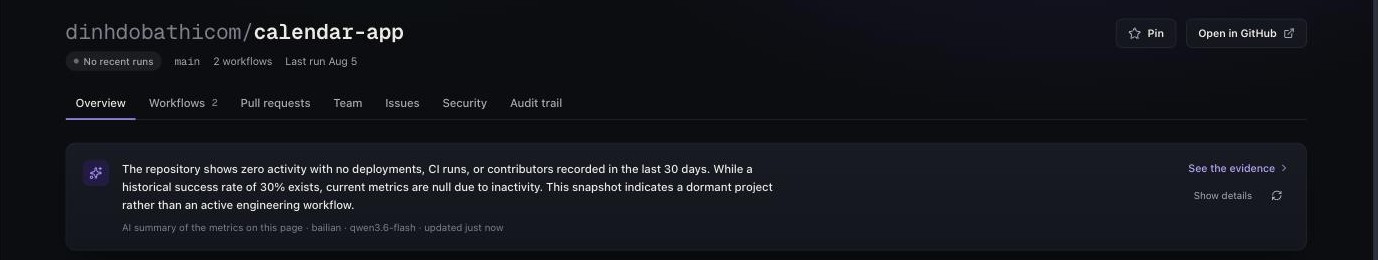
What data leaves your instance
This is the part worth reading carefully. Prompts are assembled server-side from a typed snapshot that allowlists its fields — anything not in the list cannot be sent, and the test suite fails the build if a forbidden field appears.
| Sent | Never sent |
|---|---|
| Aggregate metrics (DORA figures, success rates, run counts, bus factor) | Your PAT or OAuth token |
| Repository, workflow, job and step names | Workflow run logs |
| GitHub logins of contributors and commit authors | Source code or file contents |
| Dates and timestamps | Workflow YAML contents |
| Risk bands and composite scores | PR or commit message bodies |
| Whether the data was partial | Email addresses |
Bring your own provider
New in v4.1.5In organization mode, Settings → AI Provider lets a team point GitDash at its own account: provider, model, API key, and an optional base URL for a gateway or regional endpoint. Useful when the deployment's default key belongs to someone else, or when you want a larger model than the operator chose.
In standalone mode the section does not appear at all. A self-hosted personal instance is meant to work from the environment defaults with no setup, so there is nothing to configure.
The key is write-only: encrypted at rest with the same AES-256-GCM helper used for email credentials, never returned to the browser, shown only as a masked hint. Leaving the field blank keeps the stored key. Base URLs must be https, because that URL carries the key. Changes take effect within 30 seconds.
Providers and keys
Three providers are supported and tried in order; any without a key is skipped, so configuring one is enough. No vendor SDK is installed — the layer talks to each endpoint with plain fetch. Keys are read server-side only and never reach the browser: /api/ai/status reports which providers are configured, never the key material.
| Order | Provider | Wire format | Notes |
|---|---|---|---|
| 1 | Bailian (Alibaba Cloud) | Anthropic Messages API | Qwen models. Extended thinking is disabled automatically — see below |
| 2 | Google Gemini | OpenAI-compatible | Flash class is sufficient for this workload |
| 3 | Qwen via DashScope | OpenAI-compatible | Distinct endpoint from Bailian |
| Variable | Default | Purpose |
|---|---|---|
| BAILIAN_API_KEY | — | Primary provider. Unset = skipped |
| BAILIAN_MODEL | qwen3.6-flash | Also: qwen3.6-plus, qwen3.7-plus, qwen3.7-max, qwen3.8-max |
| BAILIAN_BASE_URL | token-plan…/apps/anthropic/v1 | Anthropic-protocol endpoint |
| GEMINI_API_KEY | — | Second in order |
| GEMINI_MODEL | gemini-2.5-flash | |
| QWEN_API_KEY | — | Third in order |
| QWEN_MODEL | qwen-plus | |
| AI_DISABLED | — | Set to true to hard-kill the layer regardless of keys |
| AI_TIMEOUT_MS | 15000 | Per provider attempt |
| AI_TOTAL_BUDGET_MS | 45000 | Wall-clock ceiling across all attempts in one request |
| AI_DAILY_TOKEN_BUDGET | 2000000 | Per instance per UTC day. 0 = unlimited |
thinking: { type: "disabled" }, and still reads the response's text block explicitly in case a model ignores that.Cost and rate limiting
Calls are cached for 15 minutes and fingerprinted on the snapshot, so unchanged metrics reuse the previous generation. Requests are rate-limited to 20/minute per token, and a daily token budget stops runaway usage.
How it fails
| Situation | What you see |
|---|---|
| No provider keys configured | The card is not rendered at all |
| Feature switched off in Settings | The card is not rendered at all |
| Provider is down or returns an error | A muted "unavailable" line — the page's own metrics are unaffected |
| Rate limit or daily budget reached | A muted "try again in a minute" line |
| Some metrics could not be fetched | A "partial data" badge, and the model is told to hedge |